A
In 1865 a thirty-year-old Manchester logician named William Stanley Jevons published a book arguing that Britain would run out of coal, and that more efficient steam engines would hasten the day.
It is a confusion of ideas to suppose that the economical use of fuel is equivalent to diminished consumption. The very contrary is the truth.
Watt’s engine burned far less coal per unit of work than the Newcomen design it replaced, and Britain’s coal bill went up anyway. Cheap steam was worth installing in places where it had never penciled out, and consumption climbed about 3.5% a year for eighty years running. He got the mechanism right and the magnitude wrong by a factor of nine, having taken those eighty years of growth and run the line out another hundred. Inference-cost projections do the same arithmetic.
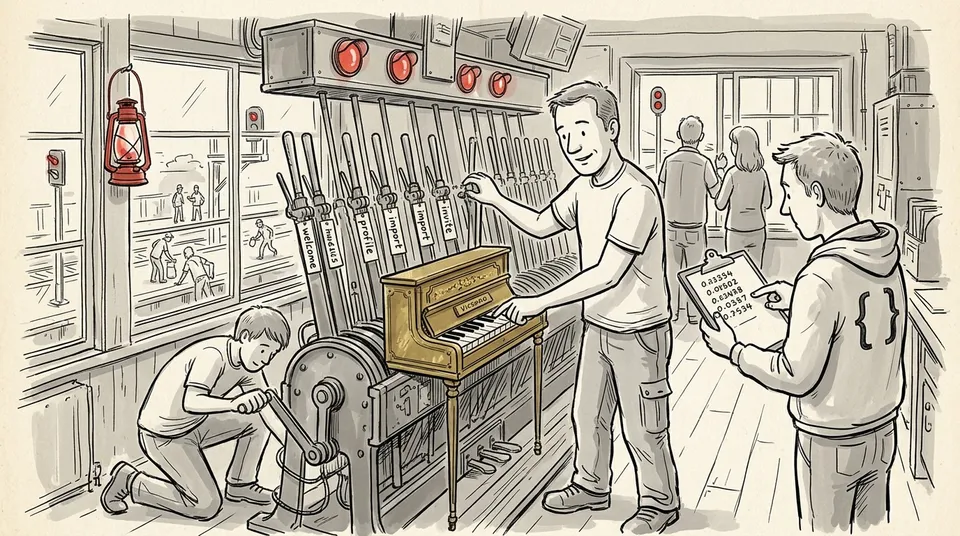
The following year he built a machine and called it the logical piano, because it looked like a small upright one. Four terms and their negations, a key for each. Press the keys for your premises and the machinery works through the combinations, drops the ones that contradict, and shows what survives. He presented it to the Royal Society in 1870 as On the Mechanical Performance of Logical Inference, and the original is still in Oxford at the Museum of the History of Science.
So the man who worked out that cheap resources get spent in places nobody would have considered also built the first machine that could run a logical inference faster than a person. Those two ideas sat in separate fields for a hundred and sixty years.
They are both back. Satya Nadella linked the paradox the week DeepSeek landed, output tokens fell from roughly $60 per million at GPT-4’s launch to roughly $0.28 two years later, and enterprise spending went up 22x anyway. Software has run this experiment on its own supply before, when Moore’s law handed the industry a doubling every two years and Wirth’s law spent it.
Which brings me to a decision that costs a fraction of a cent and lands in a fraction of a second, and to the least glamorous code in your repository.
Onboarding always starts as six screens in a row:
Welcome
   ↓
Create profile
   ↓
Connect account
   ↓
Import data
   ↓
Tutorial
   ↓
Invite team
Five years later it’s this, and the two people who remember why the third branch exists are at other companies now:
if (user.hasProfile) {
  // skip profile
}

if (user.connectedGithub && !user.hasImportedRepos) {
  // show import
}

if (team.plan === "enterprise") {
  // different setup
}

if (experiment === "new-onboarding") {
  // well... now things get interesting
}
Multiply by ten experiments, four user types, feature flags, permissions, billing states, and half-finished workflows. Congratulations, you own onboarding.
There is a model named after him. Jev is built to answer exactly the kind of question buried in that pile of if statements. People hear “AI in your app” and picture a chatbot bolted onto the side of the product. This one would live in the router, deciding which screen comes next, in a part of the codebase that has never had anything to do with AI.
Jev Doesn’t Generate Anything
Jev is the first public model from TypeSafe AI, in a category the company calls System One models, and TypeSafe is making the Jevons analogy on purpose. It does not emit text at all.
Almost every model a web developer touches today terminates in tokens:
prompt → tokens → tokens → tokens → answer
Jev’s interface is shaped differently:
application state
        ↓
       Jev
        ↓
typed decisions
+ probabilities
+ confidence
TypeSafe calls it a “frontier-intelligence function call”: unstructured state in, typed probabilistic decisions out. The practical difference is where the answer space gets defined. You’re not asking a model to describe what should happen and then writing a parser to turn prose back into something your router can use. The application declares the legal answers up front, and the model picks among them.
There are three primitives. Choice selects one option from a predefined set. Score rates something on an ordered scale. Noul estimates the probability that a statement is true. You can fire several of these at the same application state in parallel, and each answer comes back with probability and confidence attached.
TypeSafe has a much less academic name for what this buys you: smart if-statements. The average production codebase is carrying an extraordinary number of dumb ones.
Jev Isn’t the Only One
The category name is non-autoregressive decision models, and there are at least two now. Jev is the commercial one. Von is Apache-2.0, built by a developer going by wfzyx, and it implements the same /v1/systemone endpoint Jev serves, with the same three primitives. A client pointed at one can be pointed at the other.
The differences are the whole argument of this post, stated as numbers.
Von is ModernBERT-Large: 395M parameters, about 1.5 GB on disk, one forward pass, and it runs on your hardware across CUDA, ROCm, Apple Silicon, or plain multithreaded CPU. Roughly 18ms, no network. Jev is a hosted API at roughly 115ms round-trip.
Jev is considerably better at deciding. On the 49-task jabr v2 suite it scores 96.6% macro accuracy against Von’s 72.0%. On Choice routing specifically, 96.8% against 83.0%. Those gaps are not close.
So the choice is six times faster and local, or twenty-four points more accurate and remote. Which one you want depends entirely on what the decision is for.
One Transition That Thinks
Say we stop hard-coding the path and instead declare what the application is allowed to do:
const onboardingSteps = {
  welcome,
  profile,
  connectGithub,
  importRepositories,
  tutorial,
  inviteTeam,
};
Each capability keeps its hard constraints, written in ordinary code:
connectGithub: {
  availableWhen: (state) => !state.user.githubConnected;
}

importRepositories: {
  availableWhen: (state) => state.user.githubConnected;
}
Auth stays deterministic. Permissions stay deterministic. Billing and every security boundary stay deterministic. The intelligent layer never invents a screen. It picks among screens that were already legal.
So given this state:
{
  user: {
    role: "developer",
    githubConnected: true,
    importedRepositories: false,
    experience: "advanced"
  },

  account: {
    plan: "team"
  },

  onboarding: {
    completed: ["welcome", "profile"]
  }
}
the application asks one question instead of walking a tree:
decideNext({
  state,
  allowedSteps,
});
and this developer skips four screens they didn’t need:
Welcome
   ↓
skip profile
   ↓
skip GitHub connection
   ↓
Import repositories
   ↓
skip beginner tutorial
   ↓
Invite team
What you end up with is a state machine with exactly one fuzzy part: choosing the next legal transition. Everything else stays as boring as it was.
A traditional state machine is wonderful precisely because it’s dumb. state + event → predefined next state. Known states, legal transitions, a system you can reason about on a whiteboard. The transition function is what rots, once the number of inputs feeding it crosses some threshold nobody noticed at the time. XState with one transition that thinks is a smaller change than it sounds, because the box stays the same shape. The model just reasons inside it.
Confidence Is a Branch
Jev doesn’t only return a decision. It returns how sure it is, and TypeSafe positions those probability and confidence signals specifically for confidence-gated automation.
That changes the architecture more than the decision does. Instead of “AI said X, therefore do X,” you write a ladder:
high confidence
     ↓
perform automatically

medium confidence
     ↓
use deterministic behavior

low confidence
     ↓
escalate or ask
We already branch on booleans, permissions, HTTP status codes, and feature flags. This is one more thing to branch on:
if (decision.confidence > threshold) {
  // ...
}
Uncertainty becomes a first-class value in control flow rather than something you hide behind a try/catch.
This Is Experimentation, and It Breaks Attribution
Product teams already do a crude version of this, and they call it experimentation.
Give an onboarding system 3 introductions, 3 account setup paths, 2 import flows, 3 tutorials, and 2 upgrade experiences, and you’ve described 108 possible journeys. Nobody ships 108 variants. You pick two, bucket users, measure, analyze, graduate one, and start over. That’s the correct thing to do, because a controlled experiment is the only tool that tells you a change caused an improvement.
But look at it from the application’s side. We’re hand-sampling a few points out of an enormous space, and the space gets much bigger once user state is a dimension. Tutorial B might be excellent for someone who has never seen the product and insulting to a developer who ships every day. Teams might do better inviting coworkers before importing anything. Someone who connected their GitHub account three months ago may not need onboarding at all.
Traditional experiments ask which experience performs better. A smart state machine asks a different question: given everything we know right now, which valid experience should this state get? Those are not the same problem, and the second one is where this idea can go badly wrong.
If an intelligent router hands every person a slightly different journey, there is no clean Variant A and Variant B left to compare, and your attribution is gone. Worse, a model predicting that an experience is better is not evidence that it is better. Prediction isn’t causation, and adaptive software makes rigorous experimentation more necessary, not less. The wiring has to keep the two jobs separate:
                    Product Goal
                         │
                         ↓

User State ──→ Smart State Machine ←── App State
                         │
                         ↓
                Allowed Experience
                         │
                         ↓
                   Exposure Log
                         │
                         ↓
                      Outcome
                         │
                         ↓
                 Experiment System
The intelligent layer chooses among permitted experiences. The experimentation system measures what actually happened. And the experiment runs one level up, on the decision policy rather than on any single page or component. One policy optimizes for time-to-value, another for feature discovery, another stays almost entirely deterministic, and those are what you test against each other. That’s a product team’s fantasy and an analytics team’s nightmare in the same diagram.
Feature flags survive all of this with a clearer job than they have today. They define what is currently legal to exist:
newImportFlow: {
  enabled: flags.newImportFlow,
  component: NewImportFlow
}
If the flag is off, the option never reaches the decision layer at all. Which leaves three responsibilities that most mature codebases currently smear together across the same tangle of conditionals:
Feature flags
"What is allowed to exist?"

Experiments
"What are we trying to learn?"

Smart state machine
"What makes sense right now?"
Pulling those apart is worth doing before you add any AI whatsoever.
Why the Doom Demo Isn’t a Gimmick
The early Jev builds look like a grab bag. Someone wired it into Doom, making decisions inside the game loop. Browser Use put it behind an open-source browser agent that finished a flight-search task in about seven seconds. Others have used it for context compaction, research classification, trading systems, and drone decision loops.
Both models have been run against ViZDoom Defend the Center, and the result inverts the benchmark table. Von averages 9.00 kills. Jev, the model that wins by twenty-four points on general accuracy, averages 5.62. In a game loop the smarter decision arrives after the demon has already fired, and a 115ms round-trip is the entire difference. Latency is accuracy when the state changes while you are waiting.
Read those as state machines and they collapse into one shape:
Here is the current state.

Here are the things you may do.

Which one makes the most sense next?
That’s Doom. It’s also checkout, troubleshooting, feature discovery, and every admin workflow you’ve ever maintained. The applications have nothing in common; the primitive underneath them is identical.
What It’s Bad At
Jev is early, and TypeSafe documents the limits plainly. It reads state literally. It isn’t for arithmetic, counting, or date math. Irrelevant context degrades its decisions. Choice questions need bounded option sets. And a type-correct answer is still allowed to be wrong.
Von documents a related one: accuracy falls off where the criteria aren’t spelled out. Give it bare labels and generic language priors fill the gap. Give it explicit, descriptive definitions of what each option means and it holds up. Both models are asking you to say what you actually mean, which is a reasonable thing for a decision layer to demand and an unreasonable thing to discover in production.
Those constraints are useful, because they rule out the lazy version of this architecture:
entire Redux store
       ↓
      Jev
       ↓
      🤞
What you’d build instead is a deliberately small decision context:
const decisionState = {
  accountType,
  completedSteps,
  integrations,
  experienceLevel,
  activeFeatures,
};
Which is just the interface-segregation argument wearing a new hat: give a module only the state it needs to do its job. AI doesn’t get you out of software engineering. It asks for more of it.
It Has to Work When the API Is Down
I don’t want onboarding, checkout, or any permissions workflow to depend on a remote API being up. If the intelligence vanishes, the application should get dumber. It should not get broken.
A 1.5 GB model sitting in your process has no rate limit, no provider status page, and no network between the decision and the decider. That makes the license an architectural detail rather than a matter of taste. Von’s licensing matters here for the same unromantic reason: a floor you cannot self-host is not a floor.
Replacing this:
if (x) doY();
with this:
if the network is working,
and the AI provider is healthy,
and latency is acceptable,
and we haven't hit a rate limit...

doY()
is not an upgrade. So the smart state machine needs a floor under it. Call it System 0:
Application State
       ↓
    System 0
       │
       ├── known rules
       ├── safe defaults
       └── local state
       │
       ↓
optional intelligent decision
       │
       ↓
valid application action
The implementation matters less than the contract: the application always knows how to continue without the model.
None of that instinct is new. Progressive enhancement and graceful degradation are the same bet: establish a dependable baseline, then layer capability on top without making that capability a prerequisite. Circuit breakers are the same bet from the distributed-systems side: remote dependencies hang and fail, so you detect it and route around them instead of letting one timeout cascade upstream.
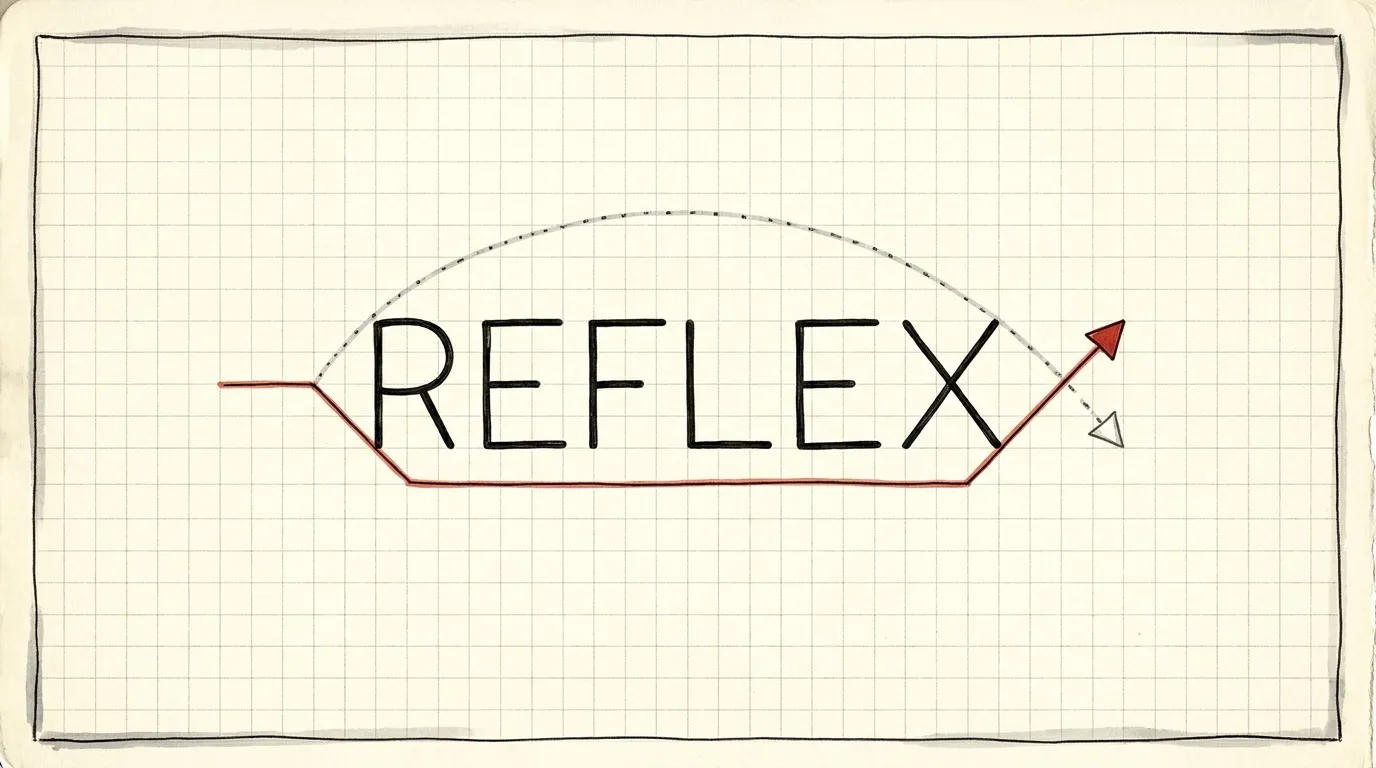
Biology got there several hundred million years earlier, and the mechanism is worth borrowing precisely. Touch something hot and your hand is already moving before your brain has processed what happened. The signal hits the spinal cord, the spinal cord fires the motor neuron directly, and the reflex arc completes without waiting on the slower system upstream. The brain still gets the information a moment later. It just gets it as a report rather than as a blocking call. You feel the pain, you learn not to grab that pan again, and none of that learning was on the critical path for pulling away.
That’s the hierarchy, and it’s the whole pattern: reflex first, judgment when it arrives. Call it Reflex. Sometimes the model answers fast enough to shape the transition. Sometimes the local rule is already good enough. Sometimes the state doesn’t need intelligence at all, and sometimes confidence is what decides whether the slow system gets consulted. The implementations differ; the principle doesn’t.
Intelligence should enhance application control flow, not become a prerequisite for application correctness.
That’s the line I’d need crossed before putting Jev anywhere near a critical path.
Use the Simplest System That Can Decide
Follow the floor upward and you don’t get a model behind every conditional. You get a cascade, where each decision goes to the cheapest system capable of making it reliably:
Request / State
      ↓

obvious deterministic case?
      ↓ yes

ordinary code

      ↓ no

fast fuzzy judgment?
      ↓

local decision model      ~18ms, in-process

      ↓ uncertain

hosted decision model     ~115ms, +24 pts accuracy

      ↓ uncertain

complex reasoning required?
      ↓

frontier LLM

      ↓ still uncertain

human
Two models with the same API and different tradeoffs turn that middle rung into two rungs, and the confidence value is what moves a decision between them. Ask the local one first. If it comes back unsure, you have already spent 18ms and you can afford the round-trip to the accurate one. If the network is down you keep the local answer and carry on, which is the whole point of having a floor.
AI doesn’t replace application logic here. It fills the fuzzy gaps where deterministic rules were already brittle, and the surrounding application decides how much uncertainty it will tolerate before escalating.
The Interesting AI Might Be Invisible
For a few years now, adding AI to software has meant adding something the user can point at: a chatbot, a copilot, a generated summary, an agent, anything with a sparkle icon on it.
Jev suggests the opposite end of the spectrum, where the AI disappears into ordinary architecture:
React
State
APIs
Feature flags
Experiments
Permissions
        ↓
tiny intelligent decisions
        ↓
React
Thousands of decision trees that currently grow a new branch every quarter could each get a small amount of judgment, while the components, the routes, and the constraints around them stay exactly where you left them. Judgment shows up in places where an API call would have been absurd: a button flow, a router, a form, a state transition, a single if.
Calling a frontier reasoning model to decide which onboarding screen comes next is ridiculous at today’s prices and latency. That is the whole bet. Price and latency are the two numbers that move, and Jevons already published what happens when they do.
I started out wondering whether Jev could make a static onboarding flow slightly less static. Where it leads: a product experience built from normal components, bounded by normal constraints, measured by normal experimentation infrastructure. One layer picks the path through it, and a deterministic floor underneath keeps working when the model goes away.
I haven’t shipped this. As far as I can tell, nobody has. But that’s the architecture I want to try: a progressively intelligent state machine, perfectly capable of running on reflex, with better judgment when it’s available.
Ordinary software stays in charge. Every once in a while, one of the transitions gets to think.